Search results for tag #llm
"for the moment... there's considerable belief in the power and potency of #LLMs: a belief that is convenient for a lot of people but also fundamentally irrational" — I'm very slightly misquoting @iris_meredith here, but I doubt this will cause offence.
There's little that's "inevitable" about AI | deadSimpleTech
https://deadsimpletech.com/blog/llms-arent-inevitable
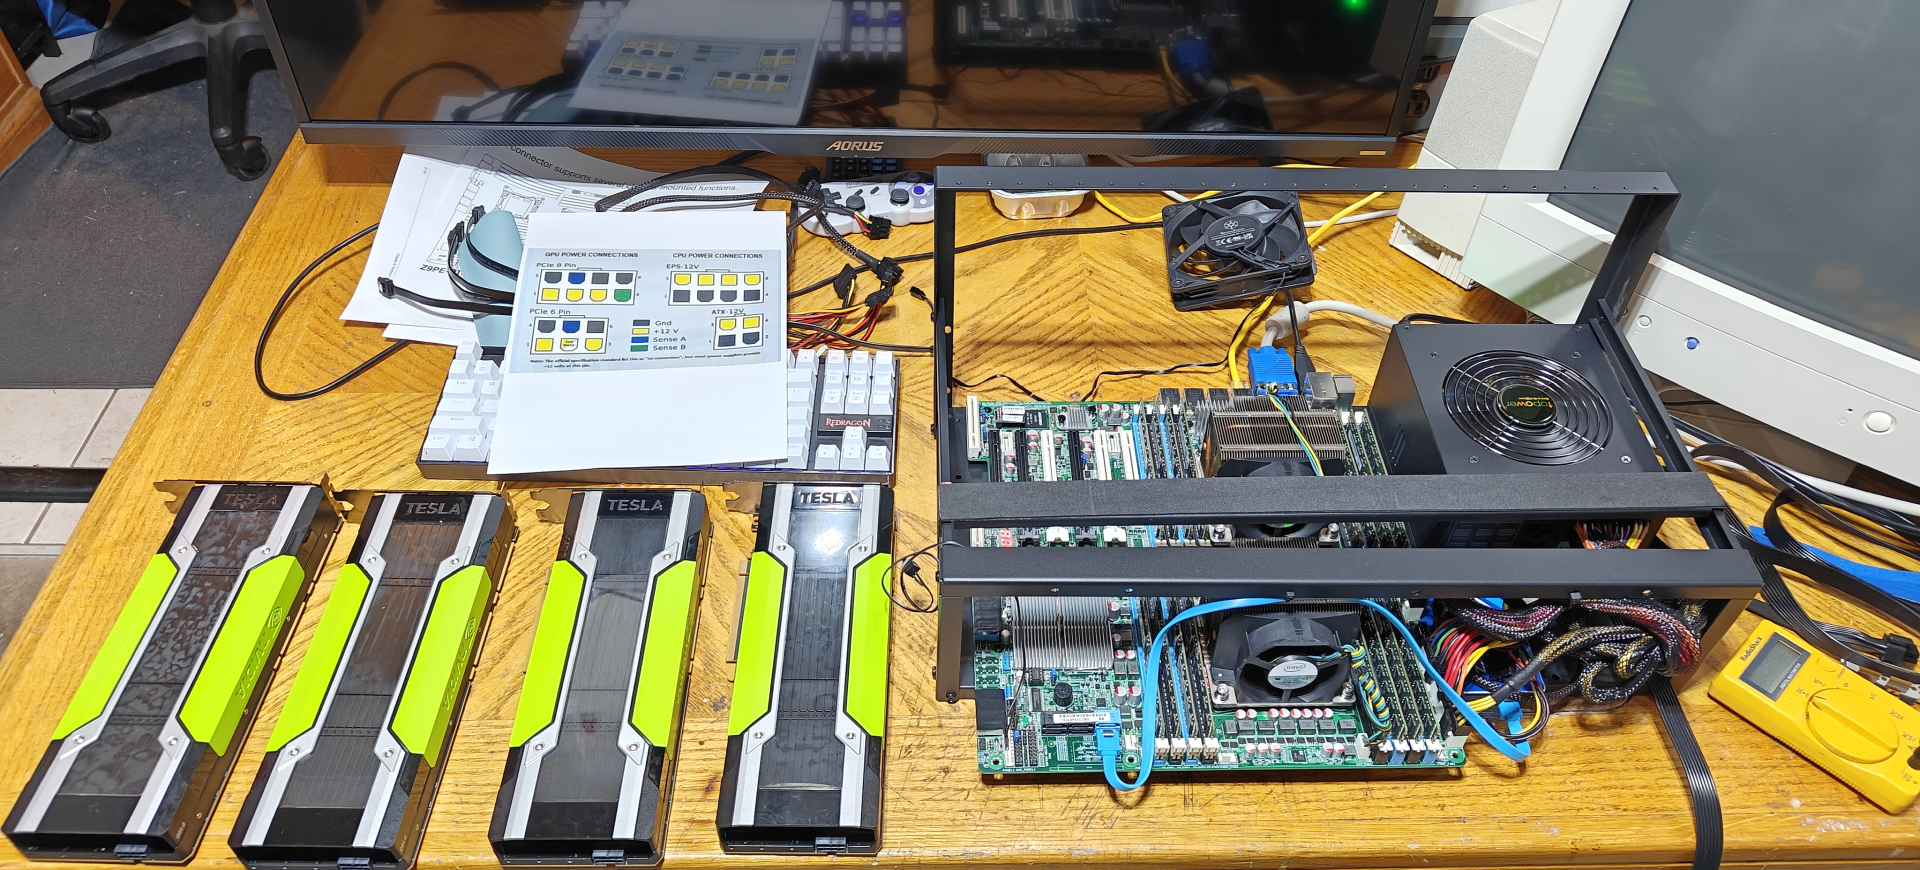
The mining rack is assembled and the P100 GPUs are here. This is the SolarAI-V2 local LLM server in assembly.
This is the hardware stack:
-Asus Z9PE-D16 motherboard
-CPU: 2x Intel Xeon E5-2620 V2 Processor
-GPU: FOUR NVIDIA Tesla P100 16GB PCIe (64GB VRAM)
-RAM: 128GB DDR3
-Storage: 120GB SSD for OS
-Storage: FOUR striped 500GB WD Velociraptor HDDs for models
-OS: ubuntu 26.04 server amd64
It will run my Hermes/Home Assistant, and is not used to generate slop.
#AI #homelab #homeassistant #llm #hermesagent #selfhosted #selfhosting
Alt...
An overhead, eye-level photograph captures a custom computer build workspace on a wooden tabletop. On the right side, an open-air metal chassis houses an Asus Z9PE-D16 dual-socket motherboard equipped with two Intel Xeon E5-2620 V2 processors, 128GB of DDR3 RAM, and an attached power supply unit with a visible top-facing black fan. The motherboard's green circuit board connects internal blue cables and various power wiring bundles.
To the left of the test bench, four NVIDIA Tesla P100 16GB PCIe GPUs lie side-by-side in a row on the wooden desk, showcasing their signature black and lime-green passive cooling shrouds and branding. Behind the GPUs, a white mechanical keyboard sits alongside a printed wiring diagram sheet showing pinout connections, a computer monitor displaying an Aorus logo, a loose fan, and a retro computer monitor further in the background. Near the front right corner of the desk, a yellow handheld multimeter rests beside the chassis. The computer is configured to run Ubuntu 26.04 Server AMD64, utilizing a 120GB SSD for the operating system and four striped 500GB Western Digital Velociraptor hard disk drives dedicated to storing machine learning models.
I just discovered a new project to let one run a massive model on stacks of old GPUs (or new ones).
https://github.com/Niko1221/Strata
If I can get this to run on my 128GB DDR3 server with 4x P100 GPUs, it will be next level local inference for ~$1k.
It will run my Hermes/Home Assistant, and is not used to generate slop.
https://tech.lgbt/@Lydie/117406088335437847
EDIT: I got ~85 tokens per second on my 7900XTX. With a 120b model. Holy smokes!
#AI #homelab #homeassistant #llm #hermesagent #selfhosted #selfhosting

Here's my suggestion for overcoming #genAI #LLM burnout and anger: find a project with a strong anti AI stance & contribute to it. My personal suggestions would be 1. Servo (no need to know #rustlang - the book needs your help, too!), 2. Redox (same - docs, end user testing etc are all valuable!), or projects by @glyph
I also have a longer list of random nerd snipe topics if none of these tickle you, e.g. Cortex-M backend for cranelift :D

When I'm thinking about AI in mathematics I end up thinking about the moon landings. It's not a perfect analogy. But there are some parallels. We tend to look back at them as a somewhat collective achievement of humanity; we're right to, I think. But the concentration of wealth in one place due to an arms race is what got us over the line.
LLMs don't just stand on the shoulders of human mathematicians, they sort of *are* a distillation of everything we've written. And right now the AI industry is in a massive PR war.
I think it's at least plausible that this period ends rather quickly, as the moon landings did. I wonder how many articles were written in 1969 about how we'd all be travelling to the moon one day.
Another parallel is: what is the inherent value of putting someone on the moon? I think it's quite similar to a landmark theorem. It broadens our horizons, maybe even enables further research, but it doesn't have much to do with the price of fish.
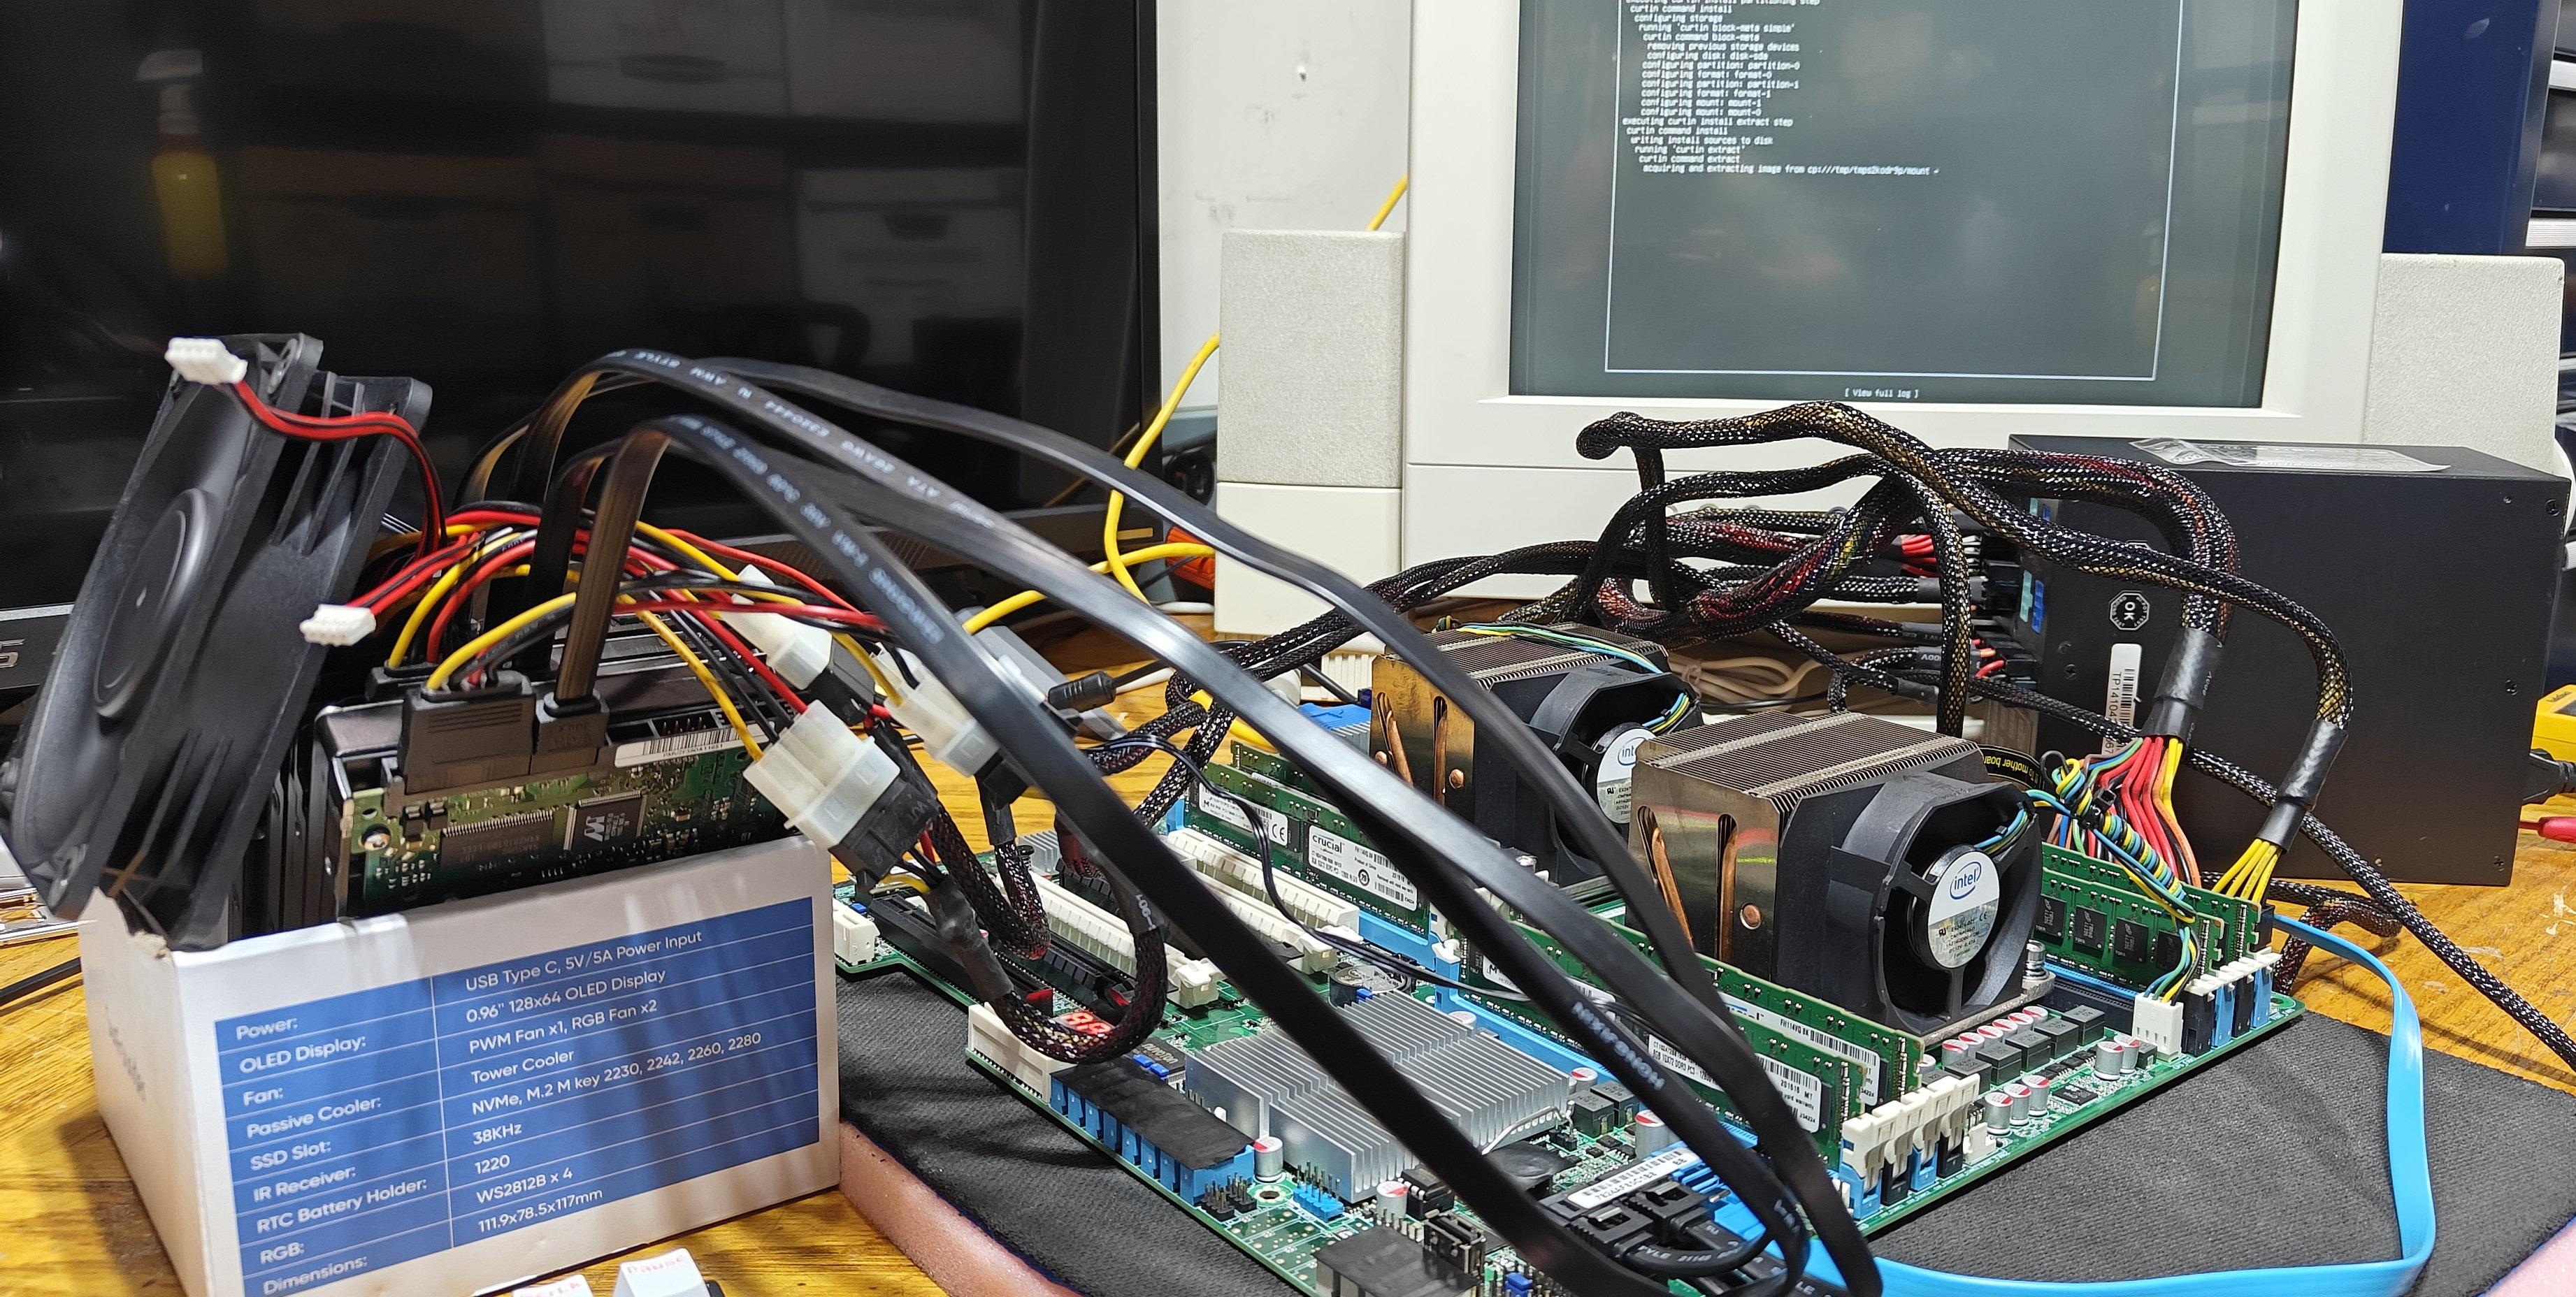
The early stages of SolarAI-V2 local LLM server in assembly.
The 4x TESLA P100 GPUs arrive tomorrow, along with a mining rack and other stuff. This is what the hardware stack is looking like so far:
-Asus Z9PE-D16 motherboard
-CPU: 2x Intel Xeon E5-2620 V2 Processor
-GPU: FOUR NVIDIA Tesla P100 16GB PCIe (64GB VRAM)
-RAM: 128GB DDR3
-Storage: 120GB SSD for OS
-Storage: FOUR striped 500GB WD Velociraptor HDDs for models
-OS: ubuntu 26.04 server amd64
It will run my Hermes/Home Assistant, and is not used to generate slop.
#AI #homelab #homeassistant #llm #hermesagent #selfhosted #selfhosting
Alt...
A dual-socket computer motherboard is laid out on a dark anti-static workbench mat as an open-bench test system, surrounded by power cabling, cooling components, and connected peripherals. The main board features two CPU sockets fitted with aluminum heatsinks topped with small cooling fans, bearing an Intel logo. Multiple green RAM DIMM modules are populated in the memory slots alongside the sockets. A large passive aluminum heatsink sits near the center of the board.
Thick, black sleeved cables and multi-colored power supply wires route across the bench, connecting to a black power supply unit placed to the right. Additional cabling arches over the board to power peripheral boards and cooling fans. To the left, a detached, large black cooling fan rests atop a white product box full of hard drives.
In the background, an off-white vintage CRT computer monitor displays white monospaced system startup and configuration text over a dark background terminal screen, showing lines related to mounting, partition extraction, and system boot procedures. Bright blue and yellow data cables run across the light wooden desk surface around the hardware setup.
Excellent.
The finances can all be summarized in two words: Ponzi scheme.
As with many bad movie plots it is much cooler to remove the vault door using a ridiculously costly laser strapped to a shark duct-taped onto a skateboard than it is to use mundane explosives.
It isn't the ridiculously costly hacking capabilities that are a danger. It is the lackadaisical and irresponsible behavior of developers who are so gullible they think people like Sam Altman, Elon Musk, Peter Thiel and Larry Ellison are geniuses. Rather than a band of clearly disingenuous con artists and sociopaths of the highest order taking advantage of the unique window of opportunity provided by the suspension of the rule of law for grifters and charlatans.
They know they only have two years left to completely fleece the rubes before the day of reckoning arrives when the carnival leaves town. All of their published and purloined plans reflect this.
In my experience the sociopaths who occupy corner offices do more damage in the world than natural disasters, and yet we seldom do anything to stop them. Even when the intelligent among us can see them coming from outer space.
With any luck the collateral economic damage when it all unravels won't kill us all before Skynet truly comes to fruition.
https://www.youtube.com/watch?v=XEMvG2vulKg
The #LLM bubble is bound to pop. It is a matter of when, not if.

#JosephStalin would be so proud of #MarkZuckerberg. It's never been so easy to create a #kompromat of any of us now.
"Each hour, Muse updates its dossiers on you and the people you’ve mentioned in chats, messages, and emails that Muse has read. … Even people who don’t use Muse are subject to this mapping process by other people’s Muse agents."
https://time.com/article/2026/10/06/meta-muse-ai-agent-privacy/
#Muse #dystopia #privacy #AI #LLM #surveillance #massSurveillance #bigBrother #GeorgeOrwell

From the call: It turns out that #FreeBSD is very good for management and orchestration by an #LLM because its commands rarely change unless necessary. Aiming an LLM at #Linux generally means you spend four passes determining out what the equivalent of 'ifconfig' or 'netstat' are, because POLA.
Not to mention that those chat bots on web pages are generally small GNU/Linux systems running Alpine or something, because systemd is too big for what they're doing.
And yes @emaste we talked about the future of distribution sets and the possible repercussions of small jails requiring package overhead.
 boosted
The October 6th, 2026 Jail/Zones Production User Call is up:
We discussed the virtual init review, Qubes OS functionality for #FreeBSD and OpenBSD, DCH's bug fixes, if_pair news, the future FreeBSD distribution sets in the PkgBase era, LibreNMS in Daemonless, AppJail, Kyua, the #Sylve installer and Zen mode, remaining bhyve wish list items, Sylve #KDE jails, why FreeBSD is good for management by an #LLM, Sylve custom installations, DHCP option 114, and more!
"Don't forget to slam those Like and Subscribe buttons."
You can support all Call For Testing efforts via BSD Fund: https://bsdfund.org
This content is not AI generated
Take a Markdown file of appreciable length, say a thousand or so words, that has been line-wrapped at 80 characters. (Meaning, sentences start and end in the middle of blocks of text.)
Prompt your LLM with this:
"Reformat this file so that every line outside code blocks contains exactly one complete sentence."
If your agent and model can do this correctly, on your first try, please let me know the agent/model combination.
Boosts for reach appreciated.
The crisis of software development comes from two contradictory rules:
- Up-front thinking is Waterfall; we must only learn by shipping
- There's no time for rework, so everything needs to be done right the first time
Bosses thought #AI could break this contradiction. But synthetic insights and vibe code don't actually enable faster discovery & delivery. They are a (poor) alternative to doing these things AT ALL.
@EUCommission #LLM models should never be trained on content without consent of the copyright holder because otherwise, as already admitted by insiders, this amounts to theft on an unimaginable scale. Not seen since the slave trade and enclosures of common land.
That you are consulting about this is a disgrace and looks like another lobbying driven shifty scam which has become the norm in the EU and elsewhere. Paid lobbying is power for the wealthy and has no place in a democracy.
AI Software Development – What Does The Data Say? – Codemanship's Blog
https://codemanship.wordpress.com/2026/08/12/ai-software-development-what-does-the-data-say/
> Industry studies concur on the same trend, observed across hundreds of thousands of code bases and teams over multiple years – undoubtedly AI use increases coding activity very significantly, but that isn’t translating into more value being created. By the time we look at not just what gets shipped, but what gets used, we see no discernible gains.
Four TESLA P100 16GB HBM2 GPUs have been ordered for the Solar Powered LLM Server V2.0.
Total spend was around $700 for the components on eBay. I think I'll stripe 5 HDDs I find in a box to store models.
The idea is highest quality model and fastest tokens per second so when I ask my smart speakers to do automation things, it's faster. Not that the current server is bad in any way.
https://www.lydie.cc/solar-ai-server.html
#homelab #homeassistant #hermesagent #llm #localai #selfhosted #selfhosting
@krans “async” and the “semicolons, except sometimes” makes me think this is about JavaScript.
@wingo JavaScript is another reason I actually kind-of like LLMs a little bit. (The usual disclaimers still apply: yes, I agree with all the people who say LLMs are evil.)
I always cringe a bit when I hear engineers say, “I haven’t touched code in months [or years],” because me personally, I love “touching code,” I feel like I wouldn’t be doing my job if I weren’t touching code at least part of the time.
But then I think about JavaScript, and how I personally haven’t touched JavaScript in over a year now — and that makes me very, very, very happy.
So the good thing about LLMs is that you don’t have to touch the nasty disgusting code, but you can still write code by hand if you like to.
I could not resist grabbing this sucker for $400 bucks. I feel like I stole it. So I guess with 80 PCIe 3 lanes (4 full length slots) and I can stuff 512GB of DDR3 in (16 DIMM slots!), I could load 4x GPUs in there.
So, which ones? Me thinks 4x Tesla P100 16GB GPUs are being bidded on now.
-2x Intel Xeon E5-2620 V2 Processor
-64 GB DDR3 (I will make it 128 methinks)
-ASUS Motherboard: Z9PE-D16
-1100w Power Supply
-ASUS Blu-Ray MDISC Burner
Might end up selling my 2080 ti LLM server if this can crank out serious tokens per second with a big arse LLM
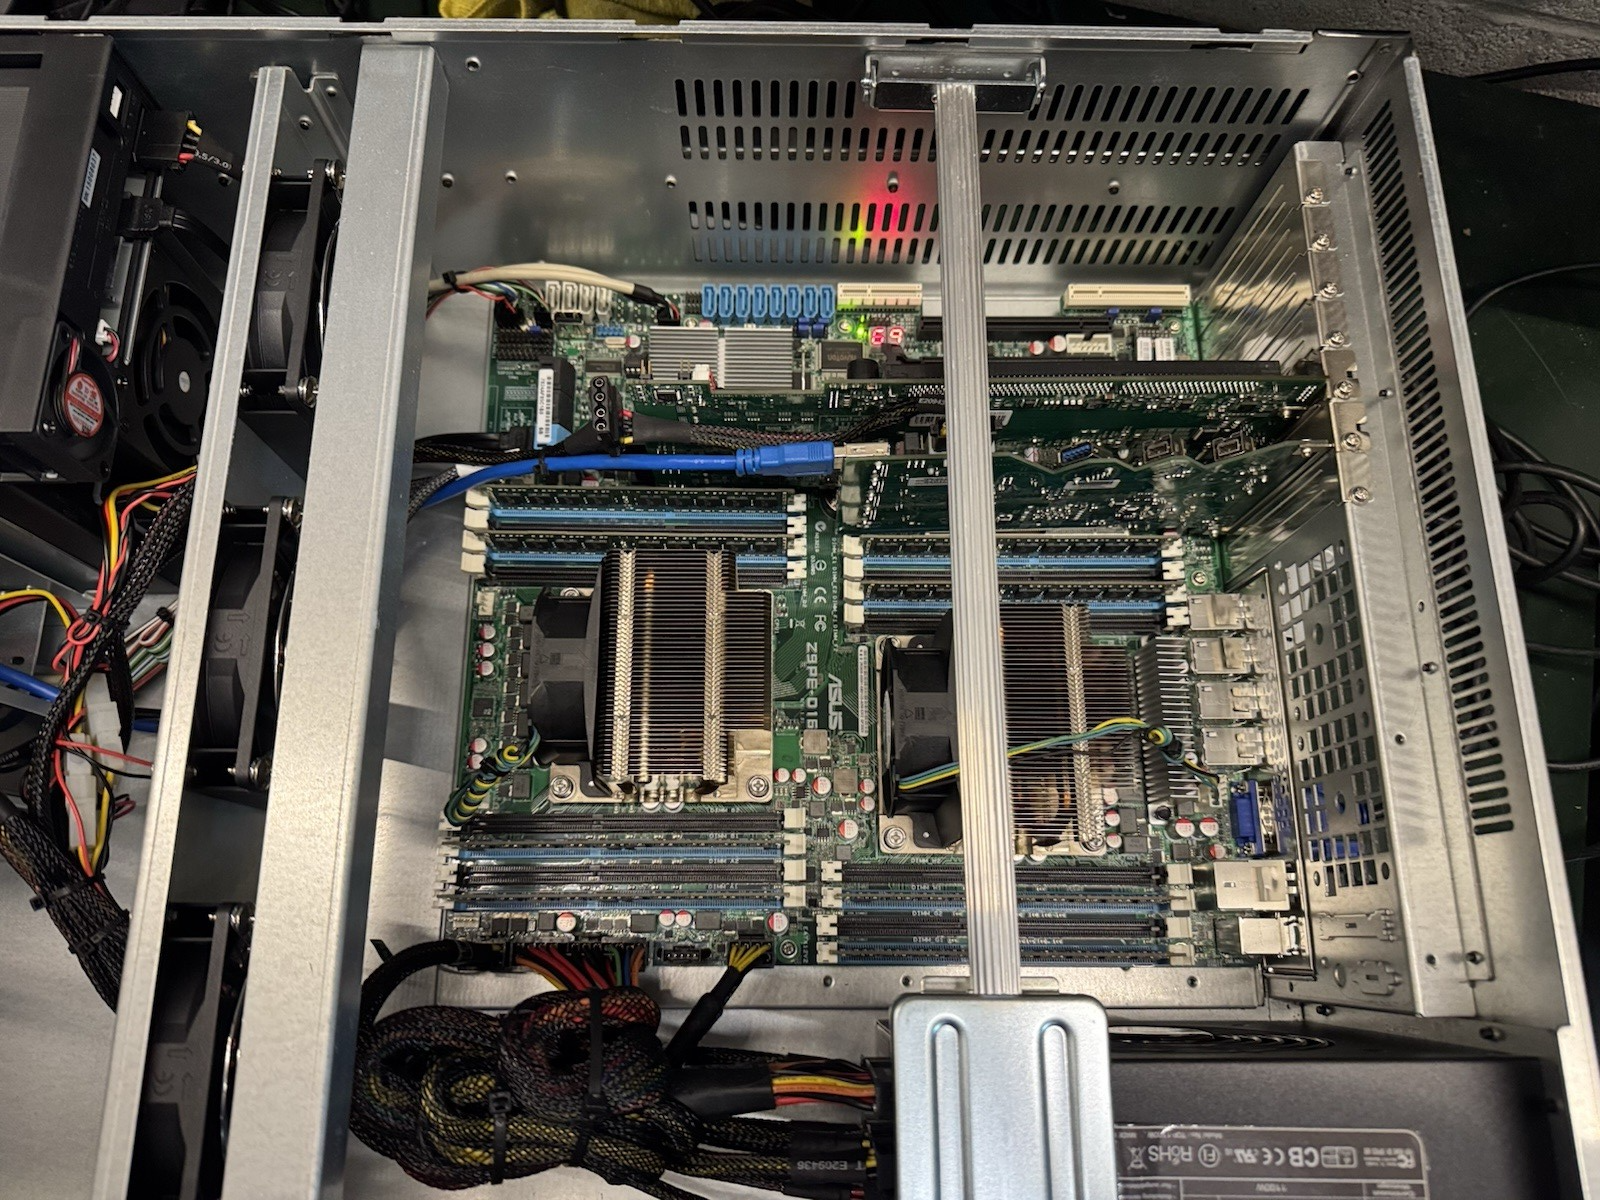
Alt...
Top-down interior view of a server chassis housing a green ASUS Z9PE-D16 motherboard. Two large metal CPU heatsinks with cooling fans sit near the center, flanked by blue and black RAM slots. Expansion cards, including a GPU and networking adapters, are installed in the PCI slots. A blue USB cable runs across the motherboard, while bundled black power supply cables rest in the lower-left corner. A silver metal support bar crosses vertically over the center. Cooling fans are mounted along the left wall, and rear I/O ports are visible on the right.
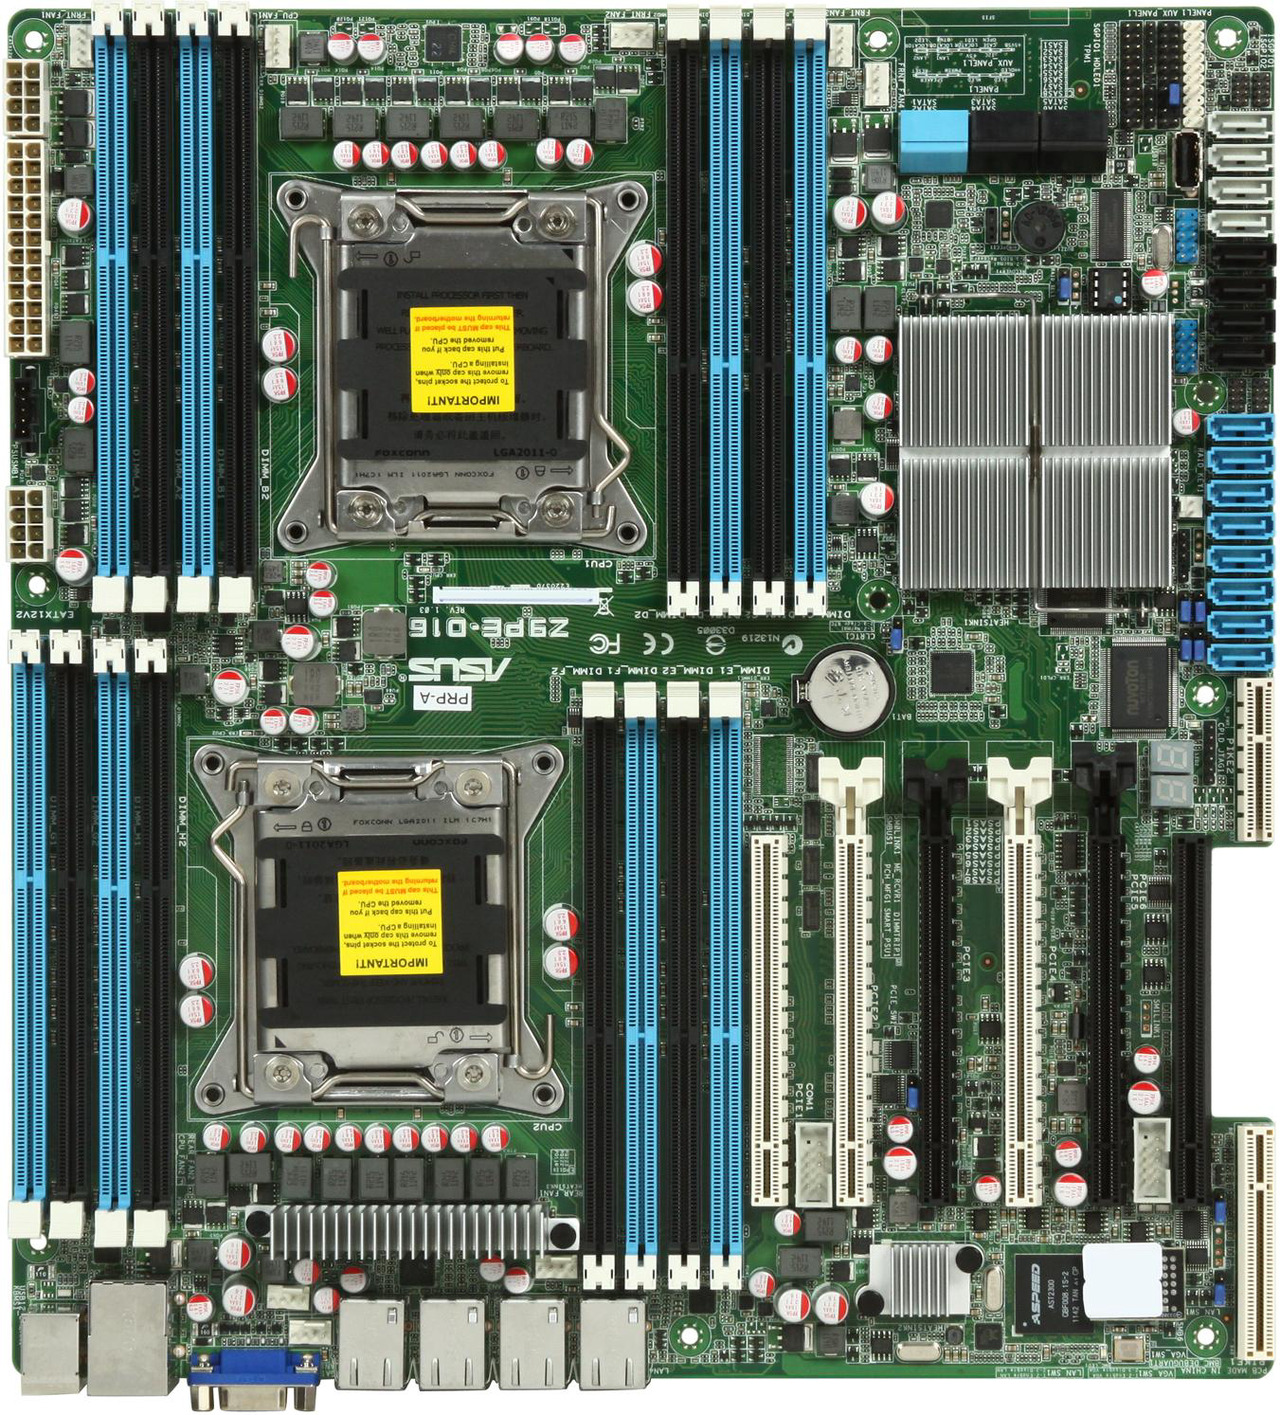
Alt...
Overhead view of an unpopulated green ASUS Z9PE-D16 dual-socket server motherboard. Two large LGA CPU sockets with yellow protective plastic covers occupy the central region, each surrounded by eight blue and black DDR3 memory slots arranged in quad-channel configurations. A large silver aluminum heatsink covers the chipset at the top right. Multiple PCI Express slots, SATA/SAS connectors, power headers, and an ASPEED chip are visible across the board. Rear panel ports line the bottom edge, including Ethernet, VGA, and serial connectors.
Updated my thoughts on (generative) AI…
#tech #technology #BigTech #IT #AI #ArtificialIntelligence #LLM #LLMs #ML #MachineLearning #GenAI #generativeAI #AIAgent #AISlop #enshittification
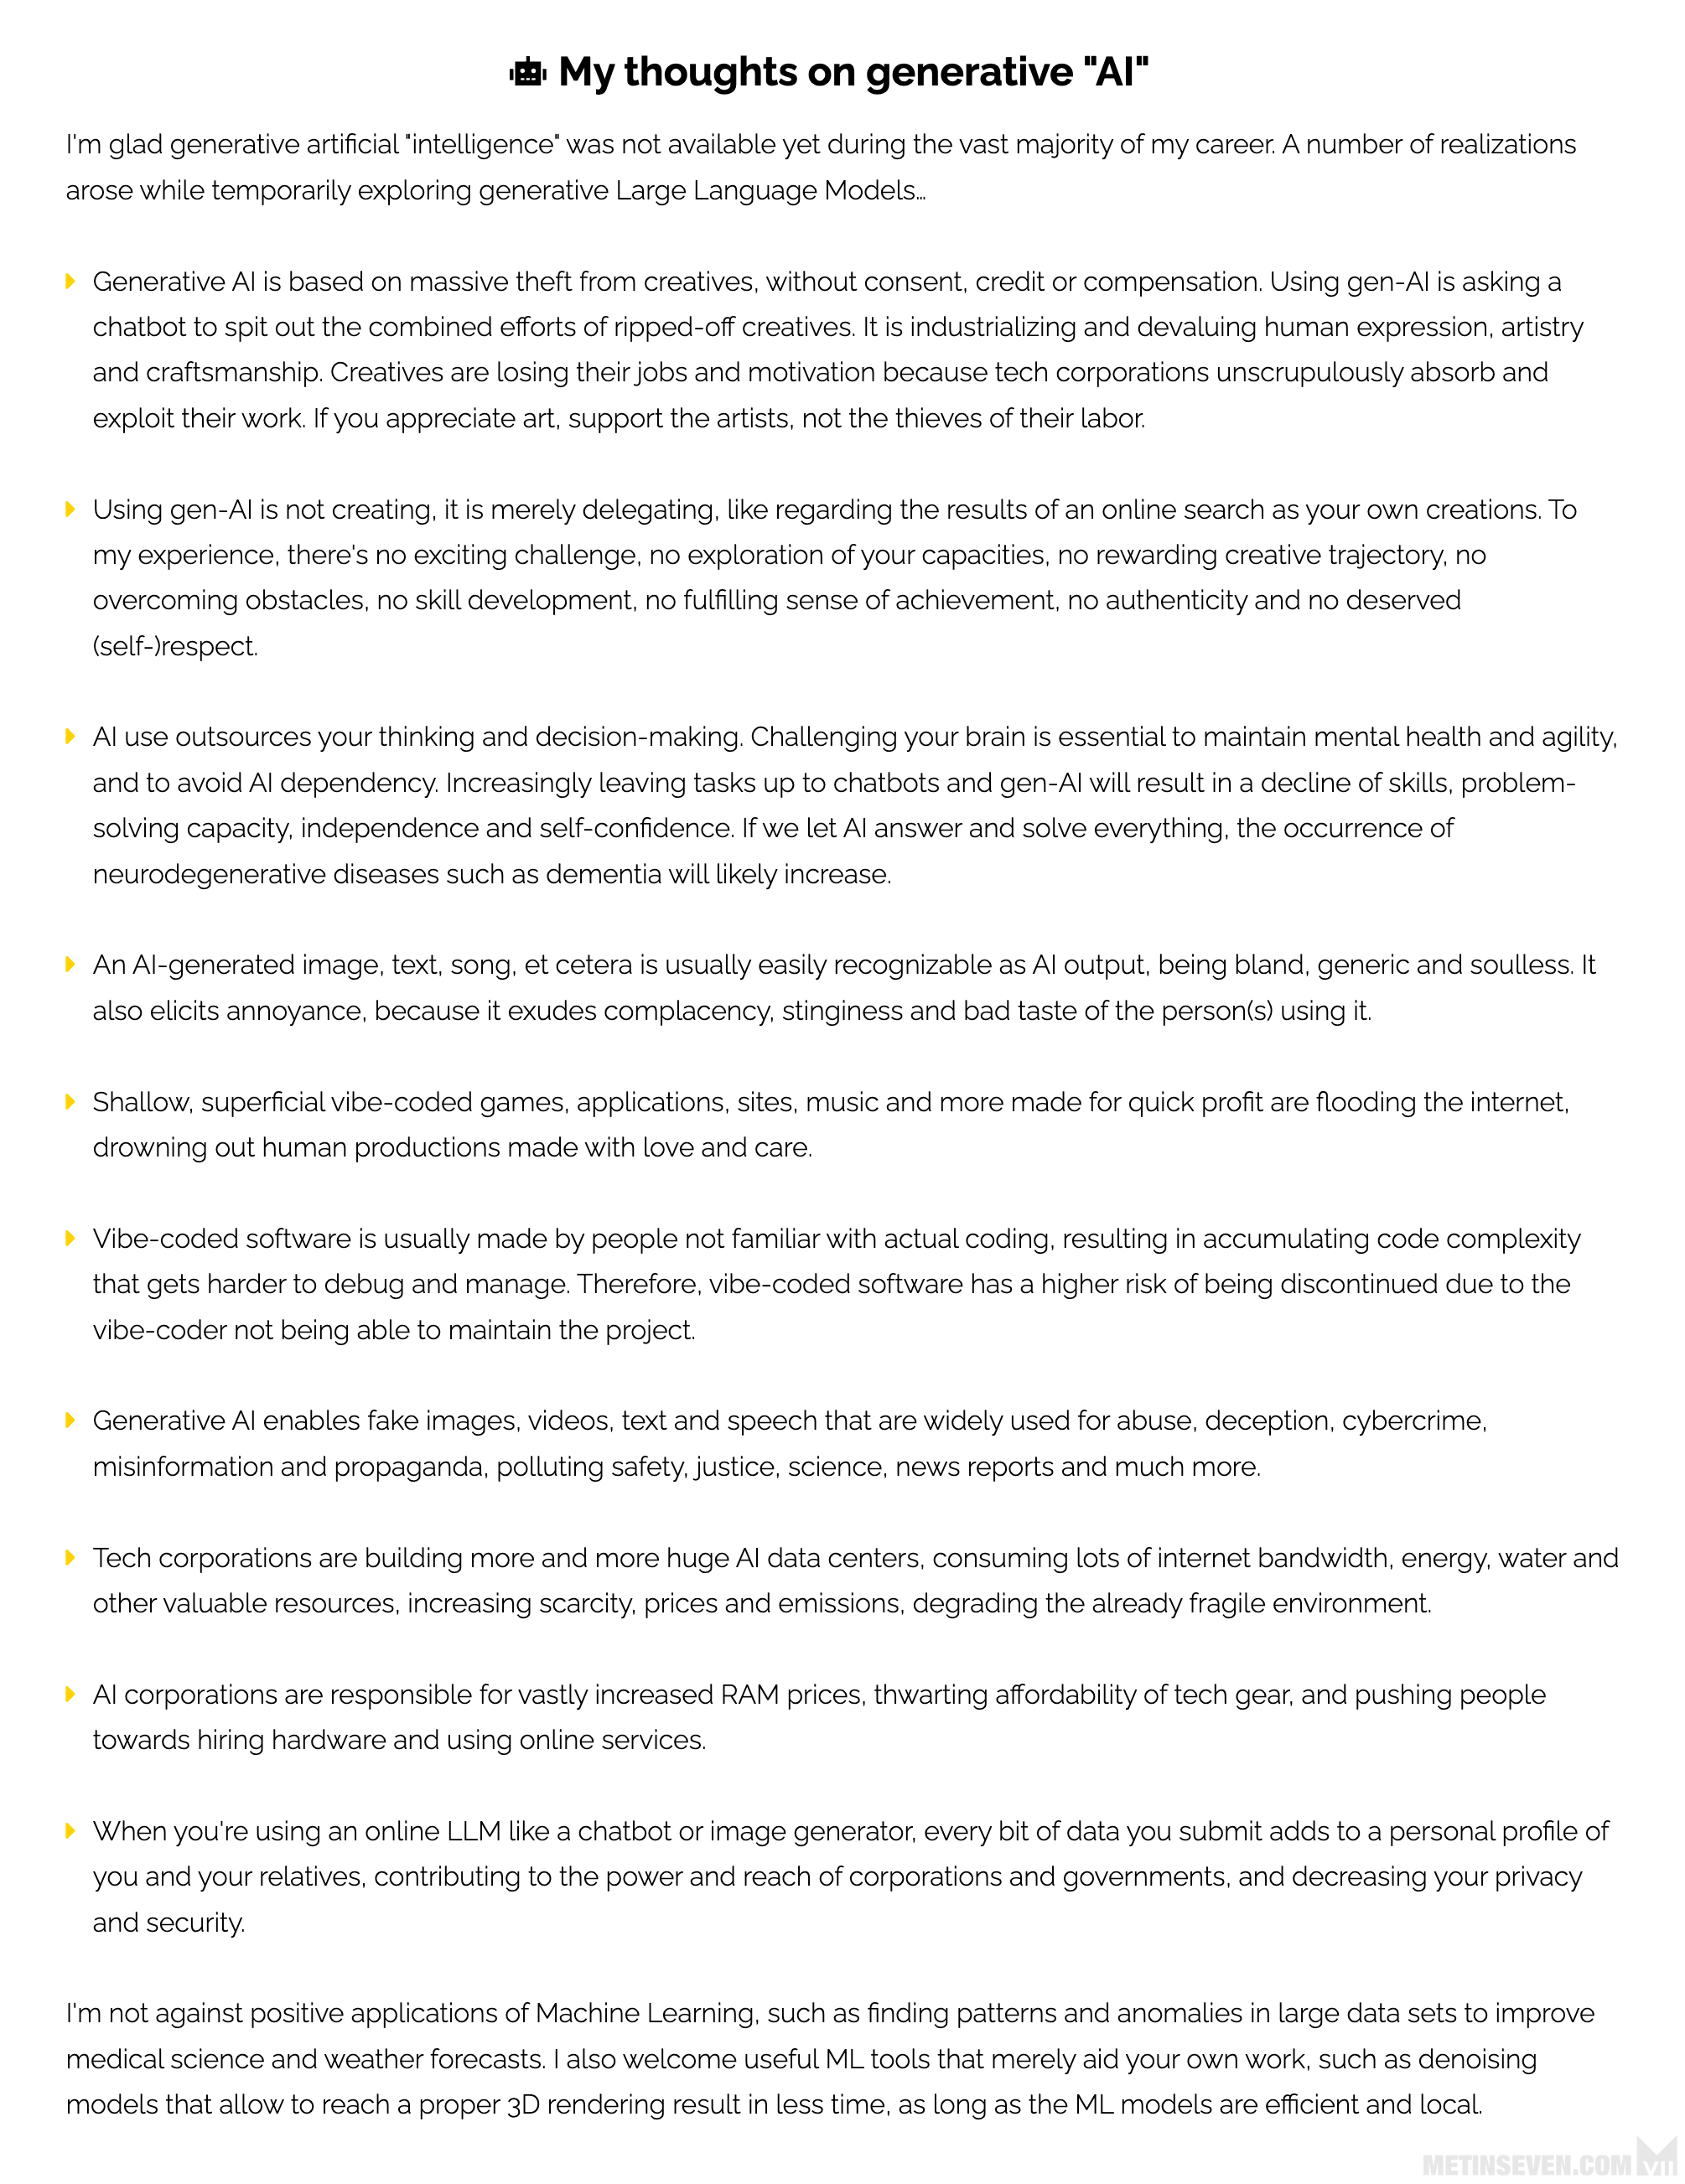
Alt...
A text with my critical thoughts about AI. It's too long for this Alt text, but you can read it on my site: metinseven.nl

New on the blog: Self-Hosted AI.
Qwen 3.8 27B on a rented RTX PRO 6000 Blackwell, one shell command, ~150 tokens per second. For most of my everyday coding, it is simply good enough now.
Also: what "self-hosted" really means on someone else's GPU. You swap trust in an AI vendor for trust in an infrastructure provider. Not zero trust, but a question I already know how to answer.
https://blog.hofstede.it/self-hosted-ai-qwen-38-on-a-rented-blackwell-at-150-tokens-per-second/
SolarAI LLM Server stats for past ~month
https://lydie.cc/solar-ai-server.html
It runs my Hermes/Home Assistant, and is not used to generate slop.
#AI #homelab #homeassistant #llm #hermesagent #selfhosted #selfhosting
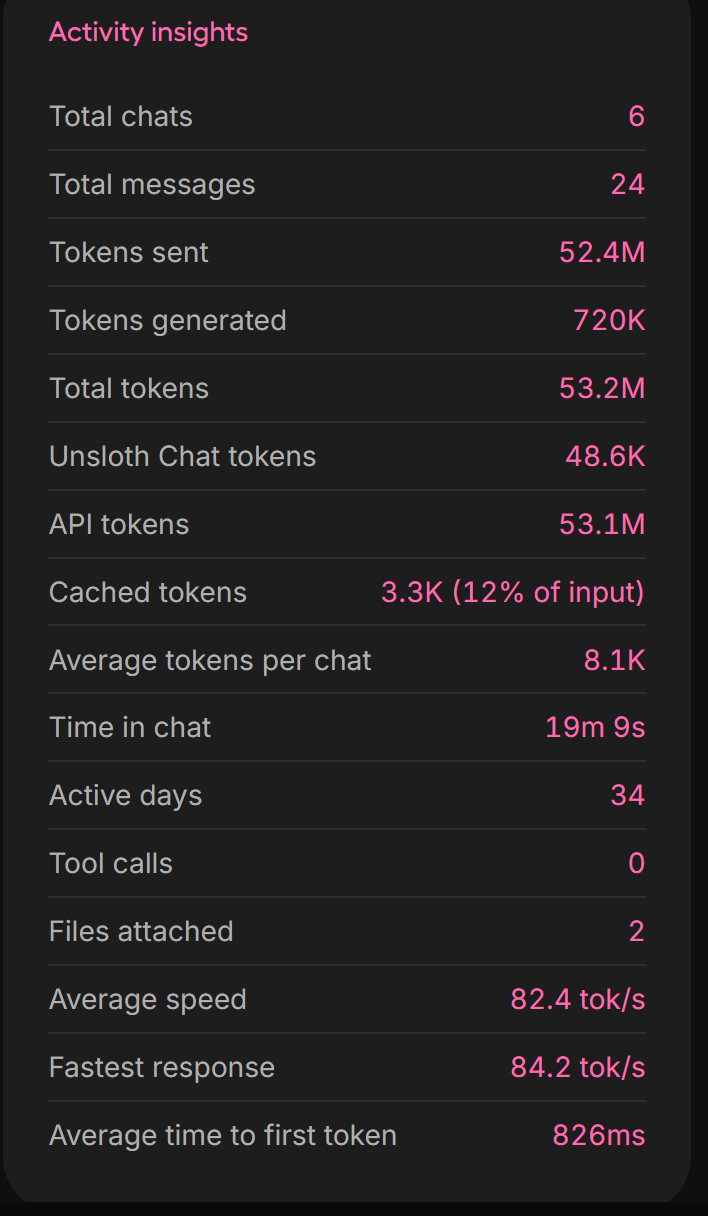
Alt...
**Activity insights**
* **Total chats:** 6
* **Total messages:** 24
* **Tokens sent:** 52.4M
* **Tokens generated:** 720K
* **Total tokens:** 53.2M
* **Unsloth Chat tokens:** 48.6K
* **API tokens:** 53.1M
* **Cached tokens:** 3.3K (12% of input)
* **Average tokens per chat:** 8.1K
* **Time in chat:** 19m 9s
* **Active days:** 34
* **Tool calls:** 0
* **Files attached:** 2
* **Average speed:** 82.4 tok/s
* **Fastest response:** 84.2 tok/s
* **Average time to first token:** 826ms

Talked to someone who has been dabbling in translating fiction. This guy was horrified when I told him that if he uses machine translation for more than dictionary checks of individual words, he can't put his name on the translation and the work is ineligible under most standard publishing contracts.
"OMG, but then it would take FOREVER to translate a novel!?!?"
Yes. You're right. That's why translators get paid.
The revenue will come from us. We will pay the cost.
Billionaires will get a profit—become even richer—and they will own the systems which will supposedly make life very different.
So what do we get in return? Fewer jobs, less control over our lives, less water, more expensive electricity, a hotter, less inhabitable planet, a bigger layer of chatbots before we can reach a human, …
And our politicians are afraid "we" will lose out of we try to regulate this?
RE: https://infosec.exchange/@david_chisnall/116939858992907996
This explains very well why "bad" code contributions by enthusiastic people can still be very worthwhile in the long run.
Also LLM's will not share a drink with you at a conference reminiscing about that time you collaborated on a piece of code, or sharing stories about stuff happening in their life.
Opensource projects dismissing these social aspects are doomed in my view.
David Gerard boosted
David Chisnall (*Now with 50% more sarcasm!*) » 🌐
@david_chisnall@infosec.exchangeOne of the open source projects I used to (many years ago, so I am not really affected anymore) has recently decided to allow AI contributions. One of their arguments is that they judge submissions on quality, not tools used.
Back when I was an active contributor (to the project and maintainer of some other parts of the surrounding ecosystem), I got a lot of submissions that were bad.
The thing is, I absolutely loved getting these because they always came from super-enthusiastic junior people. Reviewing them and giving feedback often too much longer than implementing the feature myself. The same was usually true for the next contribution too. But that shifted over time. After a few months, I started getting patches where I didn’t find anything beyond the cosmetic that I wanted to change.
Going back further, I was one of those people when I started contributing.
Measured as code contributions over the short term, maintainers working with submitters of poor-quality PRs is a waste of time. You’re taking time away from writing code to do something that produces code more slowly.
Measured over the long term, the results are very different. Far more code in that project and closely related parts of the ecosystem has been written by people who I mentored when they came along with some bad code than by me.
It’s never a waste of my time to turn an enthusiastic and incompetent contributor into an enthusiastic and competent contributor, it’s an absolutely critical part of building a healthy project. I wouldn’t have got nearly as much out of F/OSS on a personal level if I hadn’t encountered a lot of people with the same opinion when I was one of the enthusiastic and incompetent newcomers.
But LLMs are not like that. If I spend time reviewing LLM-generated code when it would have been faster to write it myself (which, to be clear, is the case on 100% of LLM-submitted PRs I’ve seen so far), then that’s just a time sink. It’s also taking away time I could be spending helping new contributors who want to actually improve, rather than just take the review comments, feed them into an opaque system, and give me back the results.


 🍵
 [


A proposal at KDE's Akademy conference for an "AI-native KDE" ignited intense debate when developer Nate Graham opened a discussion on setting restrictions for #LLM-assisted code.
The thread quickly derailed as outside commentators argued over general AI ethics rather than the proposed rules, resulting in locked comments, media misinterpretations, and an external campaign pushing for a total LLM ban.
Graham clarified that the controversial "AI-native" presentation was made by inactive past contributors and does not represent the future direction of #KDE or #Plasma.
While acknowledging legitimate concerns about #LLMs, he appealed to the community to refrain from derailing future policy discussions with broader ideological battles over AI.
Meanwhile, the debate is spreading across the open-source ecosystem. #GNOME #developer Jordan Petridis has proposed a strict policy prohibiting LLM-generated or modified contributions across GNOME infrastructure, stressing that the project prioritizes human-centric collaboration and collective software development.
https://blogs.gnome.org/alatiera/2026/09/23/the-gnome-llm-policy-that-i-want/
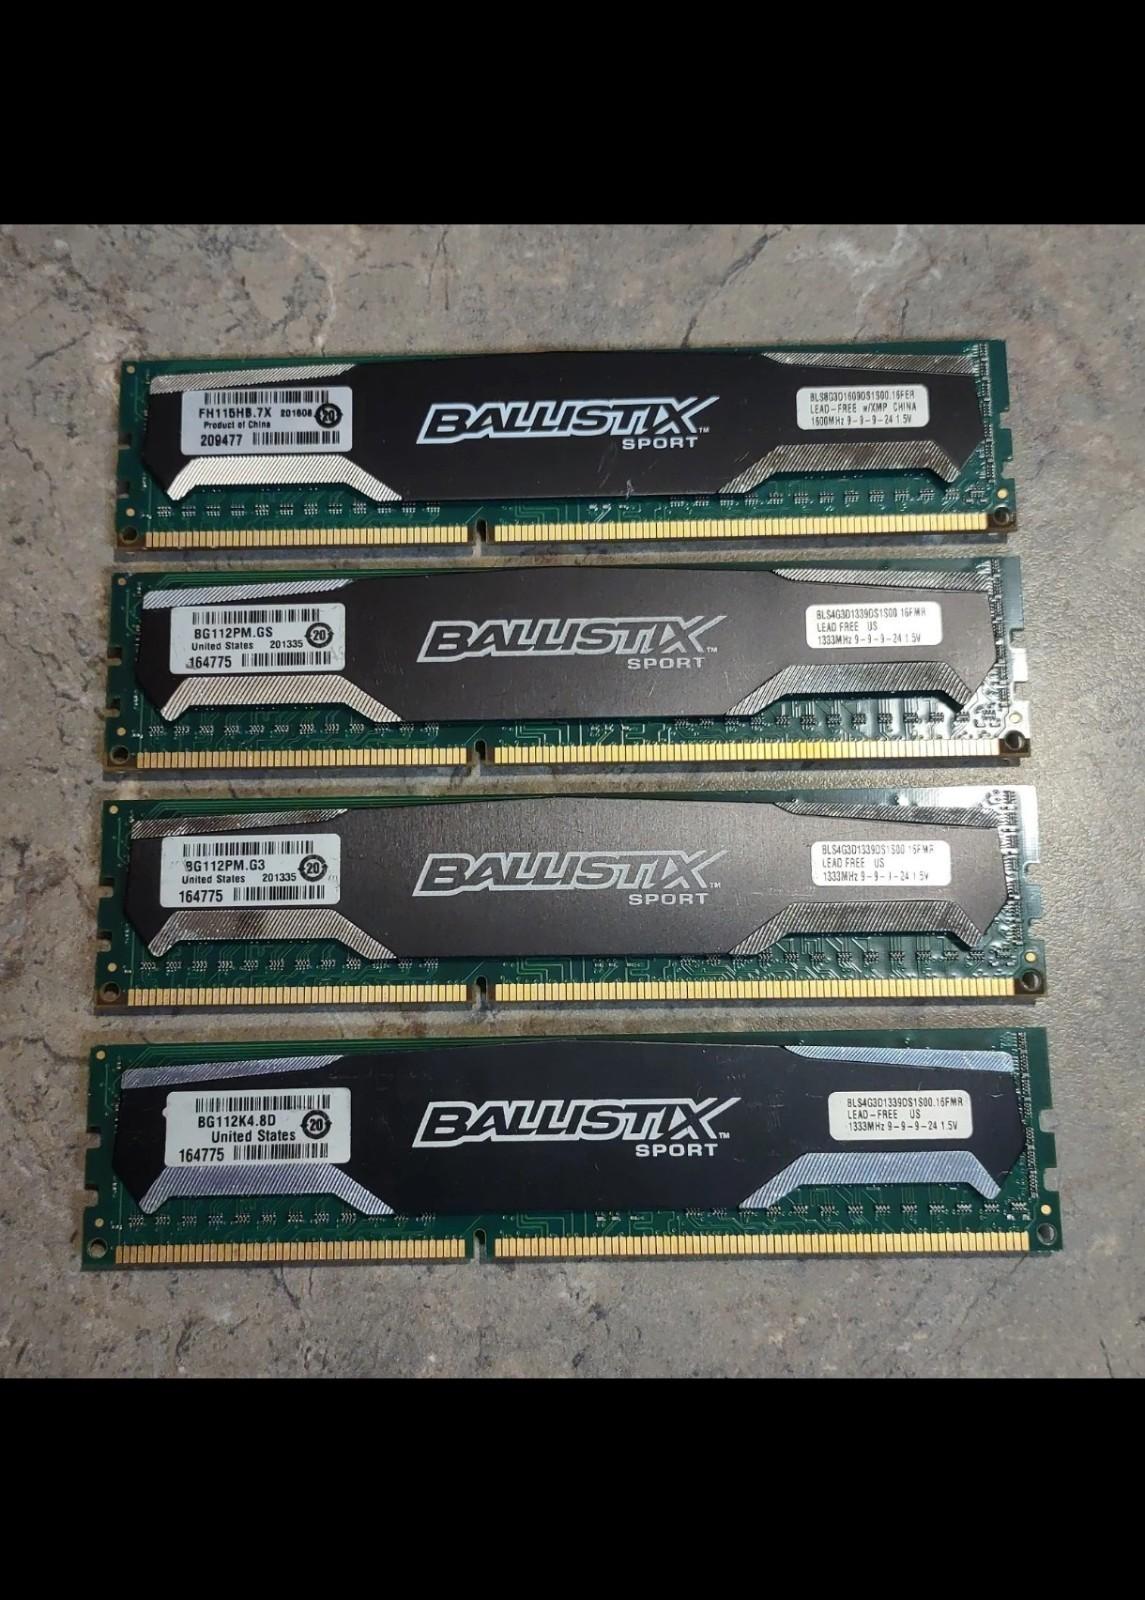
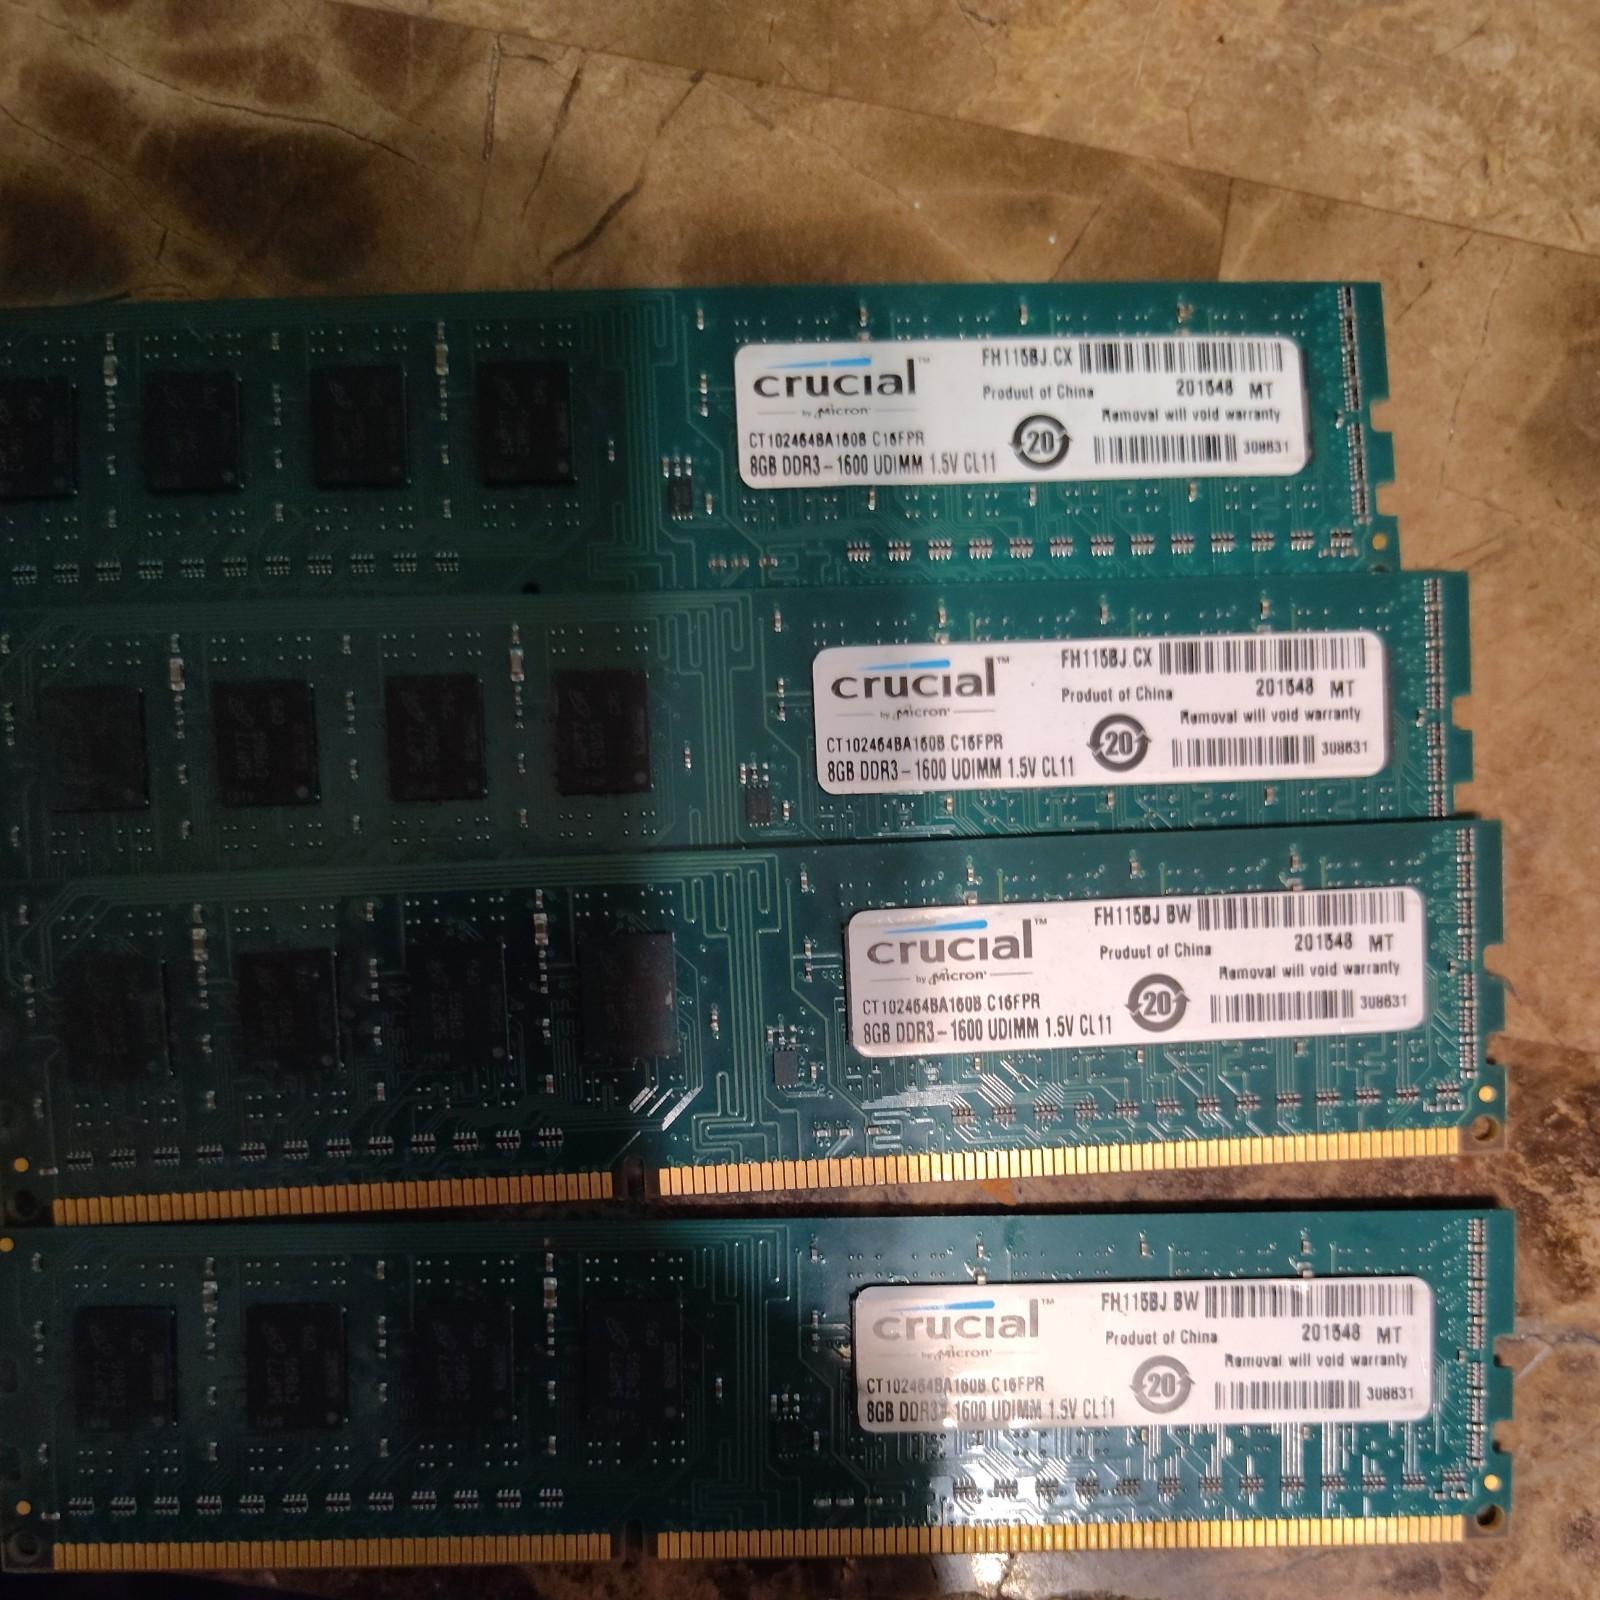
My most recent eBay wins. A total of 96GB of DDR3 (and counting). $128 spent so far.
Yup, I'm hoarding old RAM. Quad channel DDR3 is about as fast as dual channel DDR4. Lots of higher-end DDR3 mobos can take 8 sticks and they're dirt cheap (for now).
Stack a few older GPUs in a DDR3 rig (with PCIe3) and you have a nice cheap homelab LLM server like me: https://www.lydie.cc/solar-ai-server.html
EDIT: got another set. 128GB so far
#memory #ram #dram #rampocalypse #llm #homelab #selfhosted #selfhosting
Alt...
Four Ballistix Sport desktop RAM sticks stacked vertically on a neutral background. The modules feature dark gray charcoal heat spreaders with silver "BALLISTIX SPORT" branding and spec stickers showing serial numbers and barcodes.
Alt...
Four bare green Crucial desktop RAM sticks stacked horizontally. Each module shows exposed integrated circuit chips and white product stickers detailing specs (8GB DDR3-1600 UDIMM 1.5V) alongside serial barcodes.
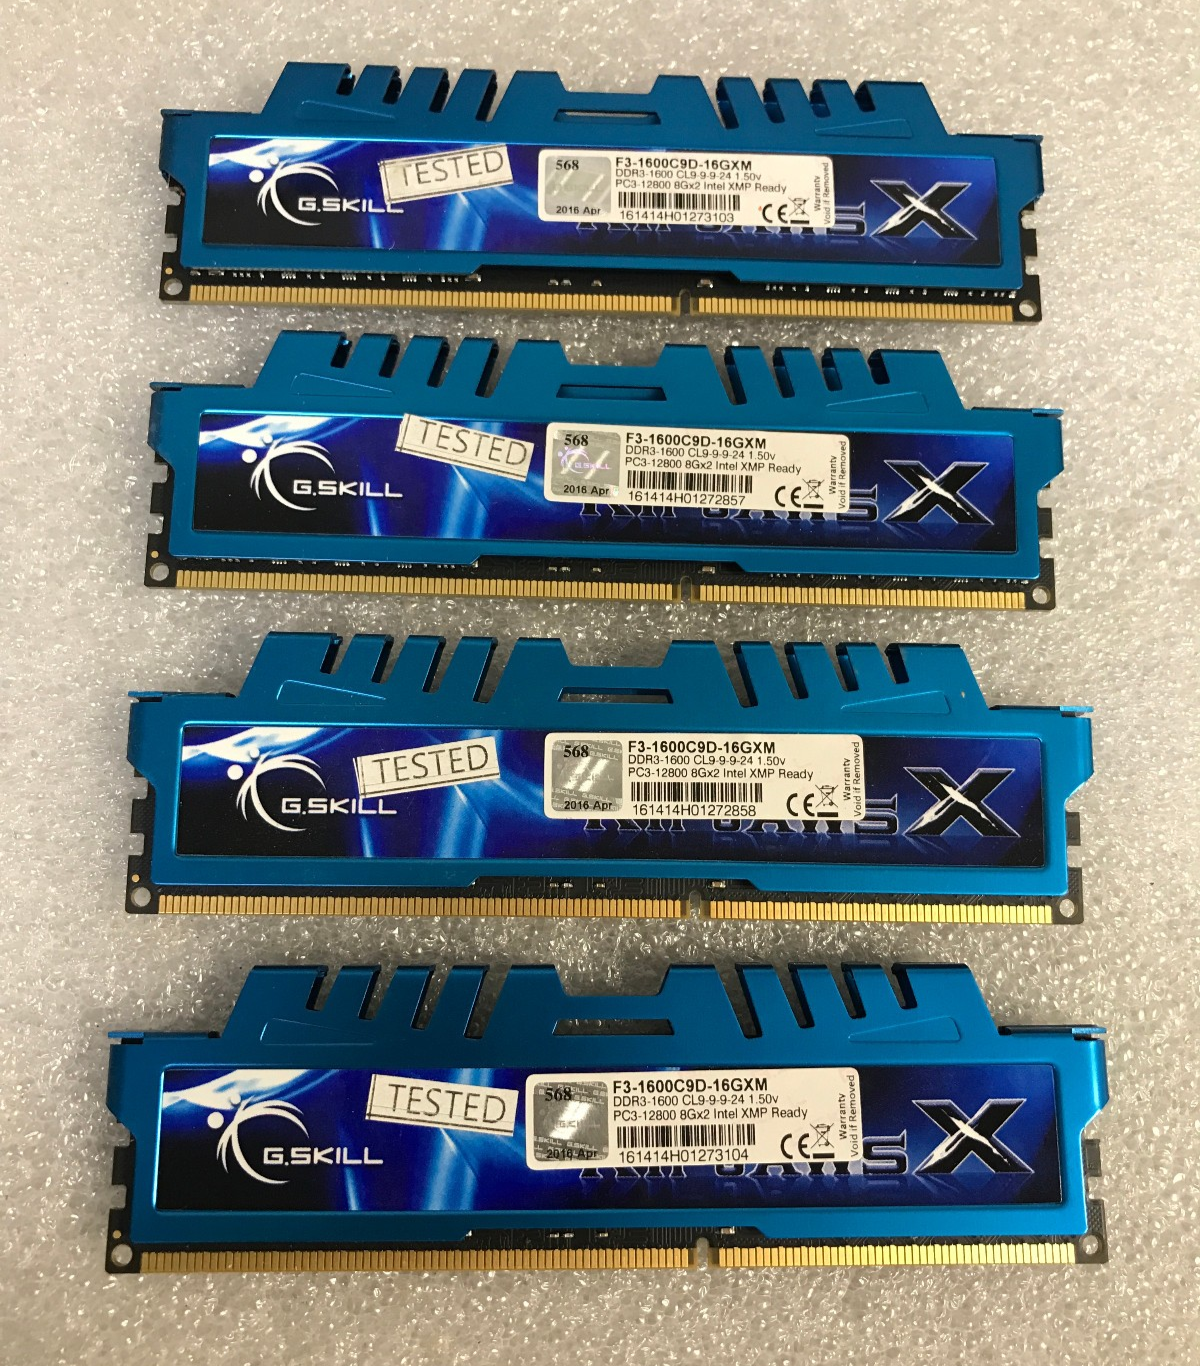
Alt...
Four G.Skill Ripjaws X desktop RAM modules arranged horizontally in a vertical row. Each stick features a metallic blue heat spreader with a stylized "Ripjaws X" logo, gold contact pins, and product specification stickers marked "TESTED".
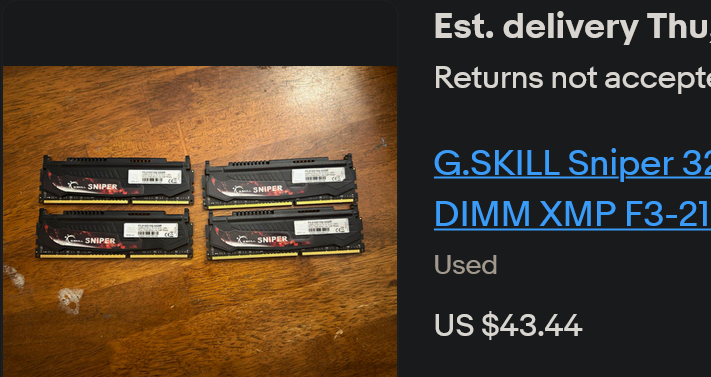
Alt...
Four black G.SKILL Sniper RAM sticks arranged on a wooden surface next to an online listing page. The right side displays product listing details, including an estimated delivery date, a "Returns not accepted" policy, item condition marked as "Used", and a price of US $43.44
@stefano Since there are no rules without exceptions, please meet my favourite #llm “Sloppy”! He’s super cute and absolutely useless! He embodies everything I think about #AI and #AISlop. He probably sucks at analysing data sets too. He just want to eat his dripping ice cream - and probably also smoke some weed. #Art #OilPainting #Painting #Robot
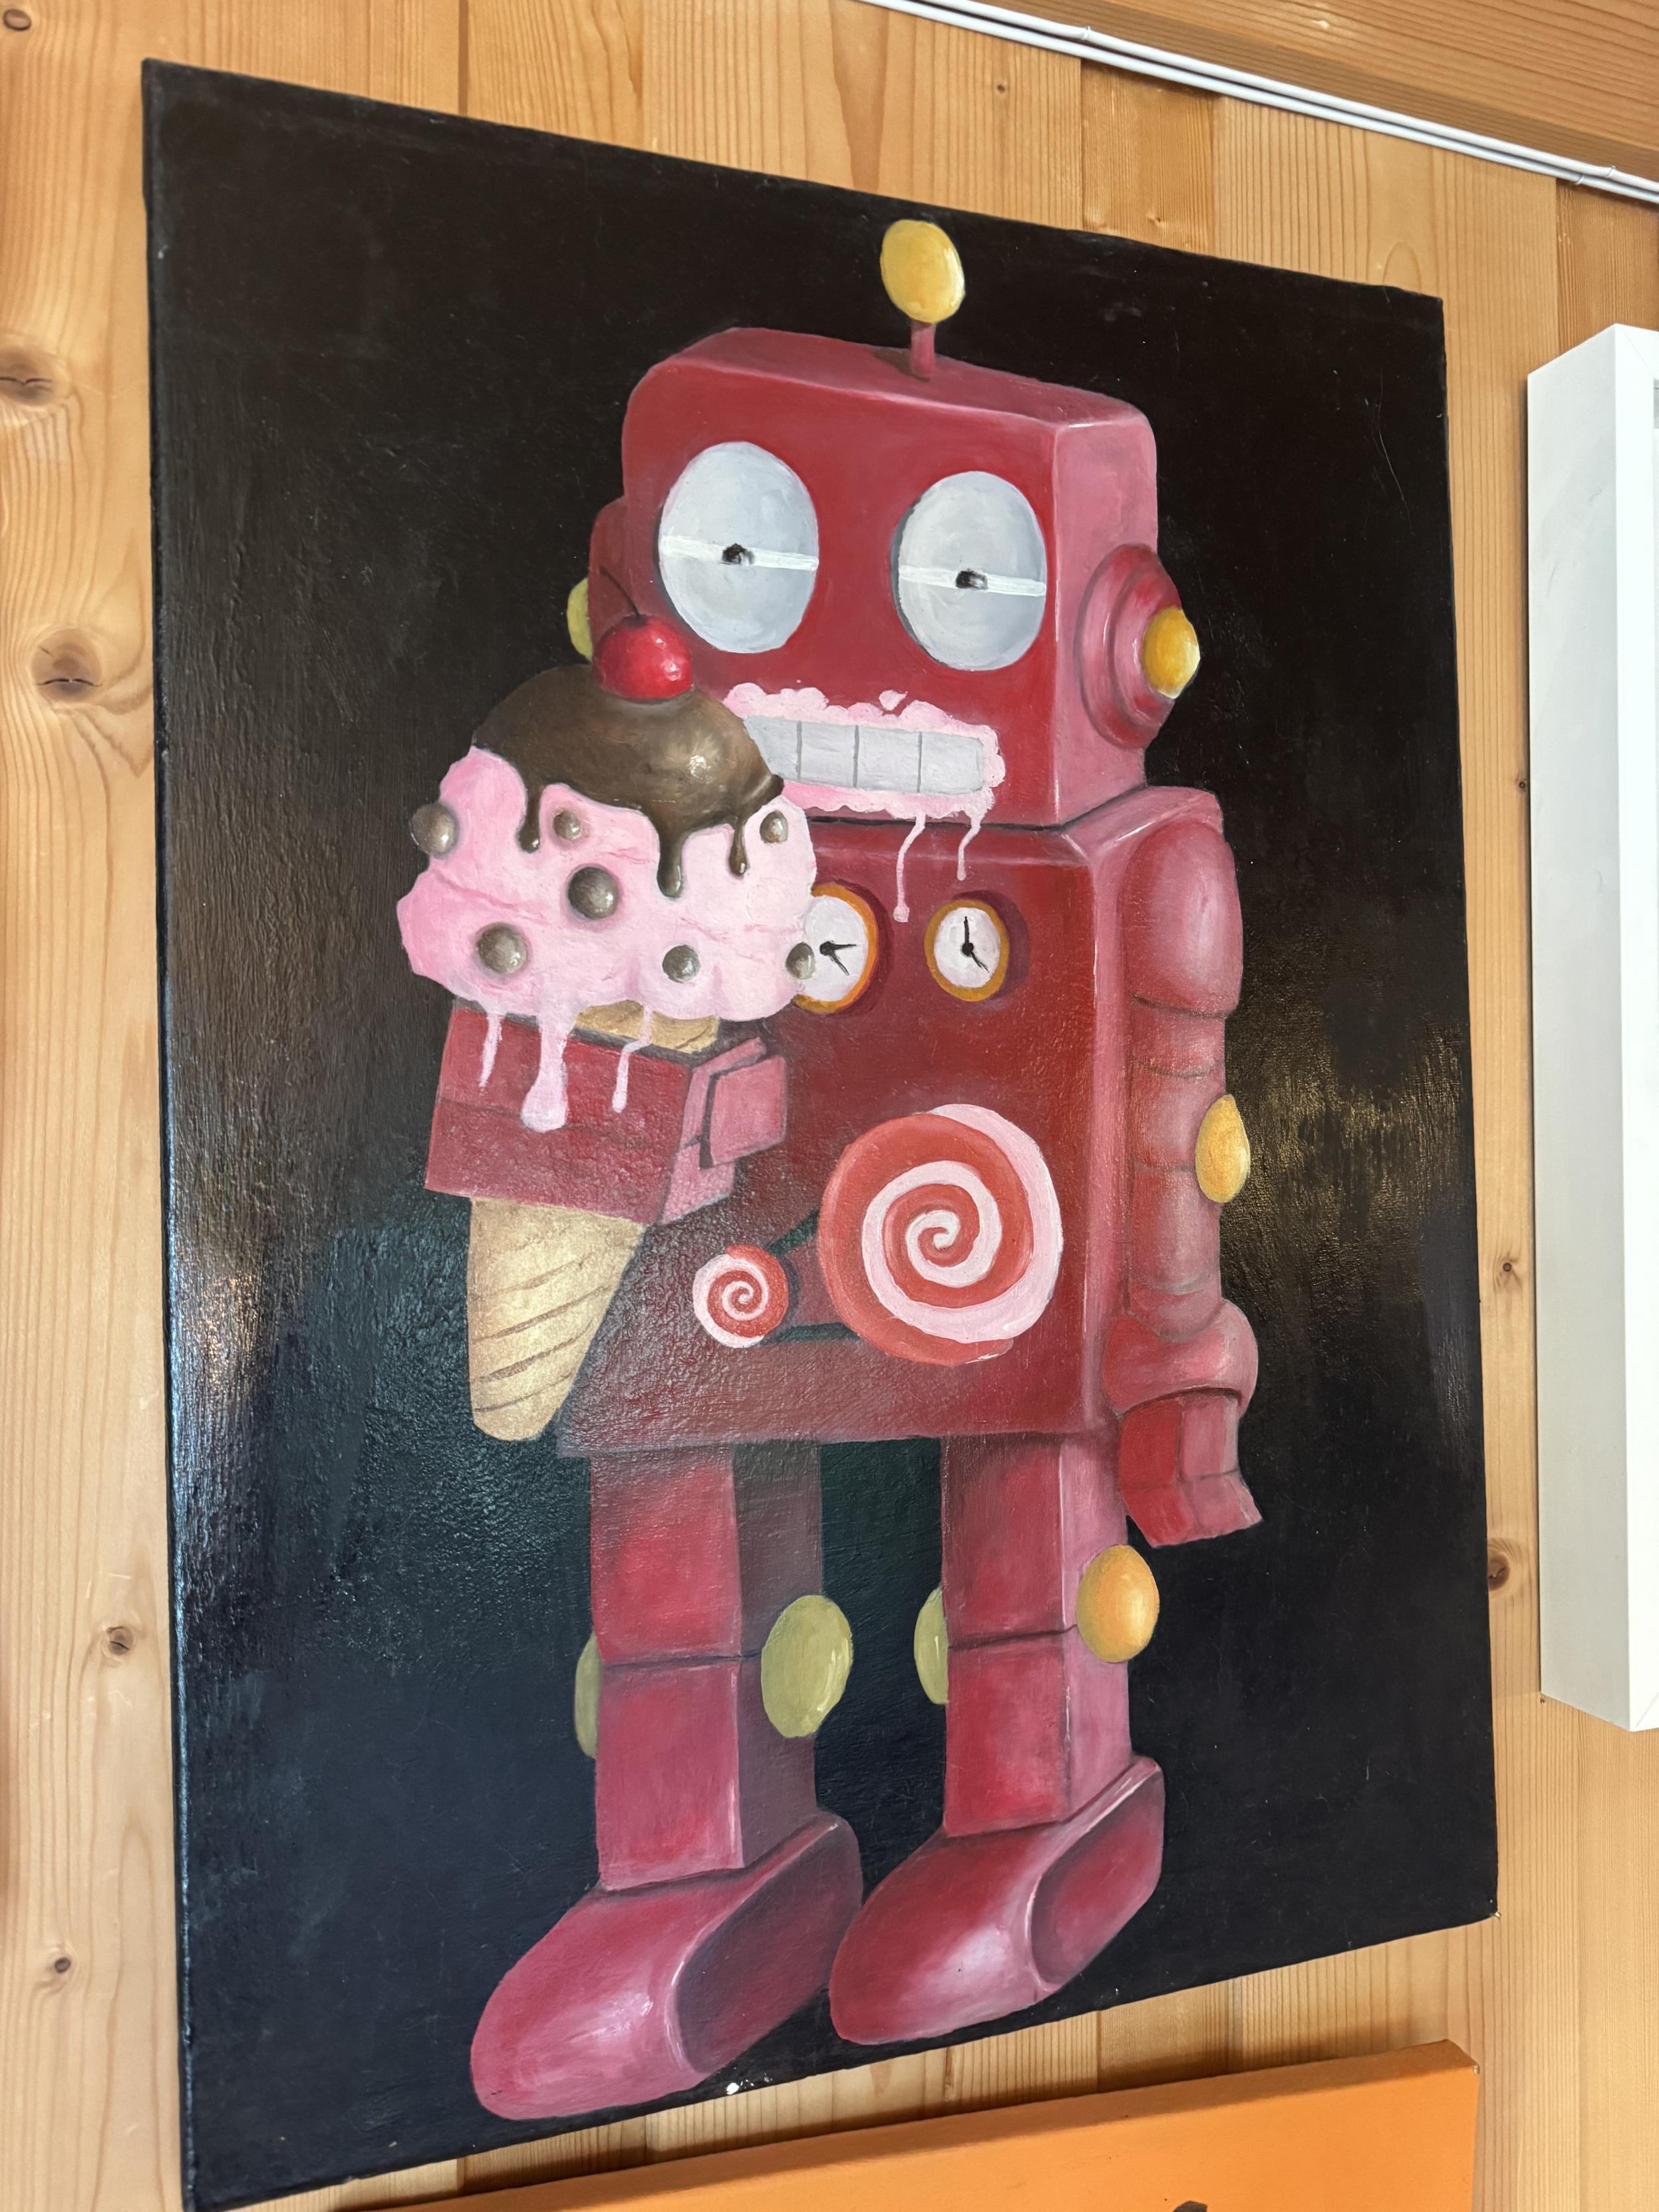
Alt...
Oil painting of a cartoonish toy robot eating a dripping and melting ice cream cone. He’s narrow eyes hints that he may be stoned beyond recognition
Running local LLMs on your Mac: what fits, what's free, and what's overkill

Microsoft is bad at writing code but they're really, really fucking good at Embrace-Extend-Extinguish. LLMs giving developers nuggets of copyrighted code to paste in to their open source projects is developer assisted Embrace-Extend-Extinguish. It's Microsoft and the BSA against Linux and BSD all over again. #KDE #LLM #LLMs #FOSS
[EDIT] Casper was an April Fool's joke. https://forums.ghostbsd.org/d/830-announcing-casper-ghostbsds-autonomous-ai-assistant[/EDIT]
I was *this* close to trying to install #GhostBSD on an old laptop, but just now I found this. Yeah, I do not want to have anything to do with these people. Apparently #FreeBSD has a very wishy-washy policy on #LLM contributions. #NetBSD has a clear ban, but I also get the impression that NetBSD is hardly an OS for casual users. Is there ANY user-friendly #BSD distro that isn't run by evil shits?
https://ostechnix.com/ghostbsd-casper-ai-assistant/
If JEV is already showing much better performance in many cases, and it does not rely on the token-by-token approach that makes conventional #LLM inference so expensive, shouldn’t the eventual cost to ordinary users be dramatically lower?
Or will companies find a new reason to keep prices high especially when people say today’s #AI pricing is still heavily subsidized and that the economics behind it are unsustainable?
It feels like the technology, the business model, and the public narrative are all moving in different directions.
HÁ HAHA HAHAAHAHAHAA SERIOUS??? REALLY?????
Pentagon Investigators Say Overreliance on Palantir AI Contributed to US Strike That Killed 123 Iranian Children. https://gizmodo.com/pentagon-investigators-say-overreliance-on-palantir-ai-tech-contributed-to-u-s-strike-that-killed-123-iranian-children-2000814477
Na plataforma de mentoria acadêmica Nova Learning, Ciência da Computação e Inteligência Artificial, "antes a escolha dominante entre os estudantes... estão perdendo terreno rapidamente, enquanto Engenharia quase dobrou sua participação ".
É uma pesquisa pequena, mas "o declínio proporcional mais acentuado é em Ciência de Software e Dados, o caminho mais tradicional de 'aprender a programar', que perdeu 44% de sua participação em 2025. Inteligência Artificial teve a maior queda absoluta de qualquer disciplina individual na pesquisa, com uma redução de 6,2 pontos percentuais.
A categoria não apresentou um declínio uniforme. Os estudantes se afastaram mais rapidamente do caminho mais associado ao trabalho de software de nível inicial, enquanto as subáreas mais aplicadas e voltadas para o ser humano se mantiveram melhor".
Digo mais, não só estudantes (profissionais que estão no ramo também).
https://nerds.xyz/2026/09/students-losing-interest-computer-science-ai-coding/
cc @carlosenog @giggio
Are LLMs still surprisingly bad at some simple tasks?
https://shkspr.mobi/blog/2026/09/are-llms-still-surprisingly-bad-at-some-simple-tasks/Last year I ran an experiment to test the ability of modern LLMs to correctly answer a relatively straightforward question. Every single one of them got it wrong. Some missed information, some made up false statements, none were right.
Of course the fanbois variously claimed that I was holding it wrong, my prompts were shit, I should have chosen better defaults, and - my favourite - that it would be better next year.
Well, next year is now. 365 days after the original experiment, let's see if these self-reinforcing-learning machines have achieved anything close to intern-levels of competence.
The Question That Started It All
I asked:
Which TLDs have the same name as valid HTML5 elements?
Why It Matters
This is the sort of question that I would expect a moderately bright teenager to answer. There exists a list which comprehensively includes all TLDs. There is a separate list which contains every HTML element.
One could either manually go through the TLD list comparing it to the HTML list, or write a tiny scrap of code to do the same.
This isn't "solve Navier-Stokes" levels of superintelligence. It's a simple but boring task which people are bound to offload onto their digital sycophants.
The Quiet Part Out Loud
How many LLM generated answers have become load-bearing without scrutiny?
People are lazy, slapdash, and some third thing to make the rule-of-three. If an answer looks answer-shaped, they'll accept it. On a simple but boring task, no reasonable human is going to suspect that a superintelligent computer has made a mistake. All the marketing says that these machines are brainier than you - so why bother?
OK, I'll write a sub-heading that sounds like an AI.
So how did the current crop do? First up Google Gemini.
The default "Flash" model came up with this:
Valid top-level domains (TLDs) registered in the IANA Root Zone Database share exact names with standard HTML elements:
.a —
<a>(Anchor/Hyperlink).app —
<app>(Deprecated HTML tag for WebAPKs/WebApps).art —
<art>(Historical/non-standard HTML element).audio —
<audio>.bar —
<bar>(Historical SVG/HTML draft tag)
Then it listed a dozen more. You don't need to be a DNS expert to know that the minimum length of a TLD is two characters - .a simply isn't valid. HTML nerds will know that art, app, and bar have never been elements. Pathetic.
So I tried Gemini's extended thinking model. Thankfully, it didn't make up any imaginary TLDs or elements. It did, however, miss the <data> element which has a valid .data TLD. It also missed map, select, and search.
So, points for not making shit up. But demerits for not being able to compare two text lists.
A friend asked Claude. That missed search and select. It didn't report any ccTLDs. You could argue that a country code like li isn't part of the original question - but I'd say that was weak justification; the set of TLDs contains ccTLDs.
A different friend (I have many!) used a different model and, while the answers looked accurate, it included this at the end:
Near misses that don't count: .codes, .forum, .pictures, .market, .navy, .press, .dell, .baseball.
I get that there's a <code> and .codes, similarly <picture> and .picture - but what are forum, baseball, and the others doing there? This is just unnecessary verbiage designed to trick the user into thinking the task has been well-researched.
If you want a laugh, take a look at Perplexity which found 54 matches - most of which were wrong.
Finally, someone asked "GPT Astra 6 Extra High" (which is a bonkers bad name for any product). It seemed to get all the elements - and made a note that two were actually obsolete.
So that's a range of modern models which are either very wrong, slightly wrong, included spurious and incoherent information, or were right.
How do you know which one to choose? How confident are you that the non-determinist computer will always produce the correct answer?
Hello Computer
Another AI which got all the correct answers, didn't make anything up, didn't add extraneous information, and didn't use weasel words was…
Siri!
FUCKING SIRI?!?!
How did a glorified Speak 'n' Spell beat all the other AIs?

Oh. It just copied the answers off a random idiot's website.
The Trick Which Was Hiding In Plain Site
Note carefully the question.
Which TLDs have the same name as valid HTML5 elements?
There's a —secret— and —some would say— unintuitive type of element. Behold the mighty power of The Custom Element.
Website authors can create their own elements like <my-custom-element> in order to extend the functionality of their site. But you can't go and create any old custom element. You can't have <mobi> or <uk>. No, there are rules for validity.
The rules say that custom elements must start with a lower-case letter, it must not contain any upper-case letters, and it must contain a dash.
And that's the whole game.
There are over one hundred and fifty Top Level Domains which match that criteria!
The Hindi top level domain of .कॉम is represented in Punycode as xn--11b4c3d. It has been present in the list of TLDs for over a decade.
Write a simple piece of JS to register a custom element.
Paste this in to your console:
JavaScript
class Example extends HTMLElement { constructor() { super(); } } customElements.define('xn--vermgensberatung-pwb', Example);
Try it again with a custom element like holiday (which is also a valid TLD) and it will fail with the error "'holiday' is not a valid custom element name". Thus it is demonstrated, Punycode TLDs are valid HTML5 elements.
One Last Thing
Perhaps you think that including custom HTML elements is a cheat. A trick question set by a bitter old man to tarnish the holy name of our new machine gods?
Verily, I submit to you one final heresy.
HTML specifically allows MathML elements in its documents.
That means we can include the following valid elements which are also TLDs: mn, mo, ms, and mtr!
Amusingly, if you go back and look at the Perplexity answer, after it barfed up a bunch of misinformation, it said:
The HTML specification also includes names from embedded vocabularies—
<math>from MathML and<svg>from SVG—but.mathand.svgare not currently delegated TLDs in the public DNS root.
So close and yet so far!
You're right, the question is unfair - and that's on me
If you think the original question was unfair, try asking "Which TLDs have the same name as elements which are valid in an HTML document?" and see if you get better results.
What precise wording would you use to ensure that a model would get the right answers? What assumptions are you making about how well you understand the problem? At what point do end up writing a thousand-word formal specification?
What does this prove other than you have too much time on your hands? (rewrite to be more friendly and professional)
Let's delve in to the problems.
- Most people don't change defaults. Telling people "you have to fiddle with the settings" just means the normal experience is rubbish.
- Humans are lazy and won't check outputs. But, crucially, they shouldn't have to! If something markets itself as a genius, why should a human have to hold its hand?
- Sycophantic models make themselves seem less fallible by giving extraneous detail in order to misdirect overworked readers. That is despicable.
- The fast models are no better than they were a year ago. There's no evidence of "trickle-down intelligence".
- Some models are better than others! But unless you constantly validate their output, you'll have no real way of knowing which ones are capable of working at a suitable level.
Look, I don't claim this question is as useful or entertaining as Simon Wilson's "generate an SVG of a pelican riding a bicycle". But I do think it is an example of the sort of real-world use-case where LLMs regularly fail.
If I give a list of one thousand different numbers to Excel, I can be sure it'll add them up correctly. If I tell Photoshop to select all red pixels, I can be sure it won't imagine some of the blues are really red.
That's people's mental model of computers - they do boring tasks quickly and accurately.
In my opinion, LLMs are still surprisingly bad - but only if you know what you're looking for and if you can be bothered to check their outputs.
(And, yes, I am still just so bored of AI!)
#AI #internet #LLM
Alt...
A confused little cardboard robot is lost amongst the daisies
I asked my solar powered HERMES AGENT on 3x 2080 TI GPUs on DDR3 to create a website about itself. This is it. https://lydie.cc/purpleai/ #AI #homelab #llm